
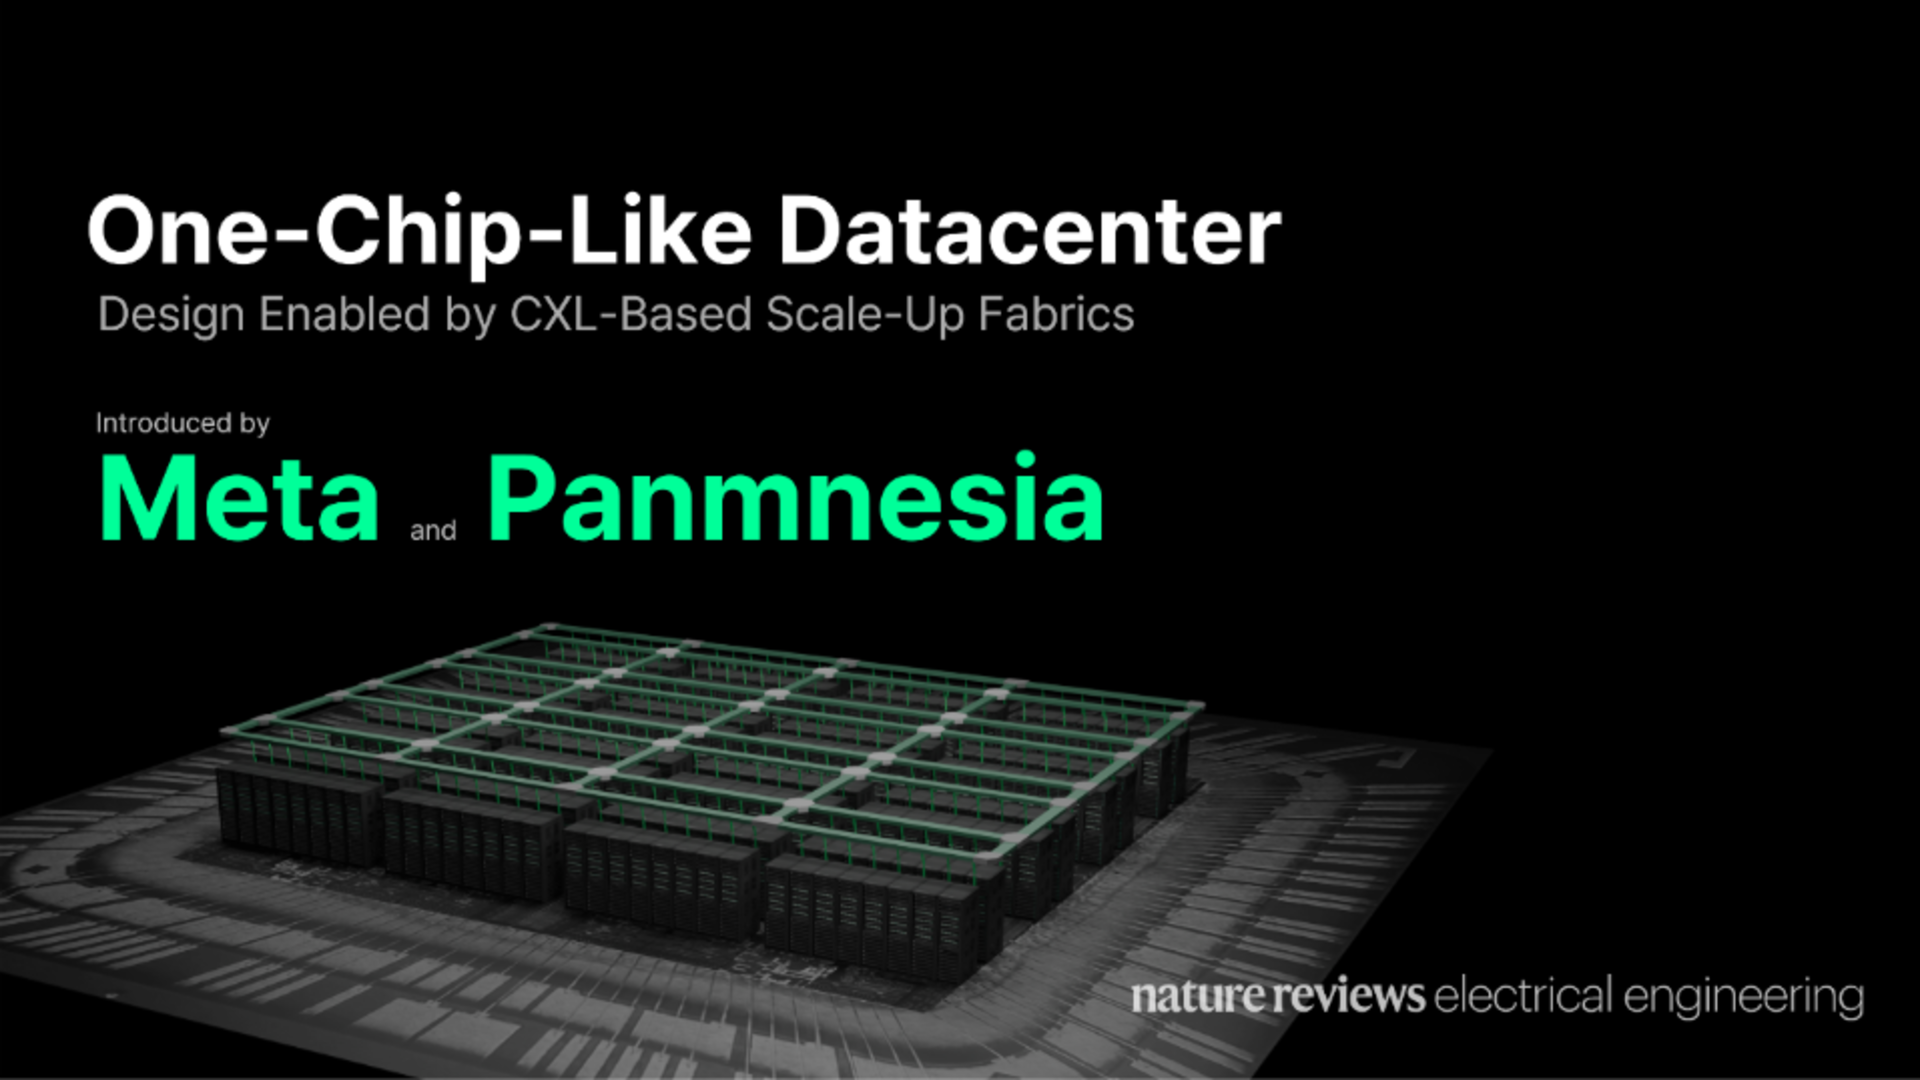
- Meta wants about 1,000 AI GPUs running in one consistent data center domain
- Panmnesia’s CXL design combines processors, accelerators, and memory in multiple racks.
- The architecture increases accelerator coordination from two devices to sixteen per processor.
Meta is working with Panmnesia on an artificial intelligence data center project that will allow thousands of processors to operate in one coherent environment.
The offering uses Compute Express Link, or CXL, to connect processors, accelerators and memory across multiple racks without using traditional network links.
The architecture can combine up to 960 AI accelerators into a single coherence region, resulting in nearly 1,000 GPUs running as a single system.
Latest videos fromTechRadar
CXL architecture expands accelerator connectivity
The project solves a problem that has become increasingly complex as AI training systems combine hundreds or thousands of accelerators processing massive amounts of data.
Each accelerator must go through repeated computational steps, meaning that one delayed component can force other devices to wait before continuing their work.
So researchers have focused on reducing unpredictable communication latency between racks, where Ethernet or InfiniBand networks typically handle connections outside of individual systems.
These networks require packet processing and software coordination, which can result in increased latency fluctuations as the workload is distributed among additional servers.
Instead, CXL provides a common coherence mechanism that allows processors, accelerators, and memory to participate in the same connected resource environment.
The proposed architecture adds dedicated hardware designed to provide greater consistency in communication paths and processing behavior across a larger fabric.
Panmnesia’s design uses a high-fan switch, a link acceleration unit, and a fabric controller to manage traffic in the system.
These components are organized into trays, blocks, and structures, borrowing organizational principles typically associated with the arrangement of functional blocks within semiconductor chips.
The company says its fabric controller and communication acceleration unit have completed semiconductor verification and the switch has been manufactured.
Its switch has also been fabricated, and preliminary silicon is said to be shipping as commercial product development continues.
Up to 960 accelerators in one coherence region
In the review, the proposed scheme is compared with the NVIDIA GB200 NVL72, where one processor directly coordinates the operation of two accelerators via NVLink-C2C.
In the Panmnesia architecture, one processor could coordinate the operation of 16 accelerators, which is eight times more than in the reference configuration.
According to the published design, about 60 such groups could then form a coherence domain containing approximately 960 accelerators.
Rack-to-rack access can also be reduced from microseconds to several hundred nanoseconds, representing a reduction of approximately an order of magnitude.
The architecture will allow you to replace individual failed devices without bringing down the entire server.
This separation may reduce the amount of running equipment removed during failures, although actual operational benefits will depend on implementation.
At the time of the announcement, Myungsoo Jung, CEO of Panmnesia, said, “CXL allows the entire data center to operate as a single computing system.”
The architecture still faces physical limitations as the CXL’s electrical signaling only reaches about seven meters at 128 GT/s with two retimers.
Panmnesia is therefore offering CXL optical links for longer distances and says it has already completed hardware performance testing for this approach.

Follow TechRadar on Google News. And add us as your preferred source to get our expert news, reviews and opinions in your feeds.